Uplink LLC: A Professional Guide to Reliable Connectivity
This guide explains how Uplink LLC supports dependable uplink operations, why service quality matters, and what to evaluate before selecting a provider. It offers objective background on uplink concepts and the typical operational requirements across broadcast, satellite internet, and enterprise connectivity—helping you compare capabilities, governance, and risk controls without relying on unverified claims.
1) What to Expect When Evaluating Uplink LLC for Uplink Services
Choosing a provider for satellite and network uplink responsibilities is less about marketing promises and more about operational maturity—engineering oversight, link reliability, security controls, and disciplined change management. This guide centers on Uplink LLC and the broader requirements typically associated with uplink operations, so you can assess capability in a practical, evidence-driven way.
At a high level, an uplink is the segment of the communication path that sends signals from a ground-based facility toward a satellite or upstream network. When that uplink is managed well, it contributes to stable distribution for broadcasting, resilient connectivity for enterprise workflows, and predictable performance for managed services.
For readers comparing suppliers and service models, the very important questions are: What exactly is being delivered? Who is responsible for monitoring and escalation? How are changes validated? How is the facility and data protected? The sections below translate these concerns into an industry-aligned evaluation framework.
To set expectations up front: a competent uplink provider should be able to explain not only “what” they do, but “how” they do it, “how they know it is working,” and “what they do when it isn’t.” In the uplink world, silence during an incident is often more expensive than a brief outage because silence can delay diagnosis, prolong impact, and complicate accountability. A mature provider will usually have a ready response structure and a repeatable operational rhythm.
In practice, the buyer’s job is to make the evaluation specific. Instead of asking for generic reliability commitments, ask for mechanisms: how metrics are collected, what thresholds trigger human involvement, what the escalation tree looks like, what configuration changes require approval, and how rollback decisions are made. If Uplink LLC (or any provider) can’t provide this level of operational clarity during evaluation, it is a sign that you may inherit uncertainty during operations.
Also, remember that uplink services can vary widely. Some vendors focus primarily on RF facility operations (keeping transmitters and antennas within spec), while others act as end-to-end partners who also manage coding, transport encapsulation, integration with downstream systems, and ongoing performance management. Your evaluation should treat these differences as fundamental, not incidental.
2) The Core Role of an Uplink in Modern Connectivity
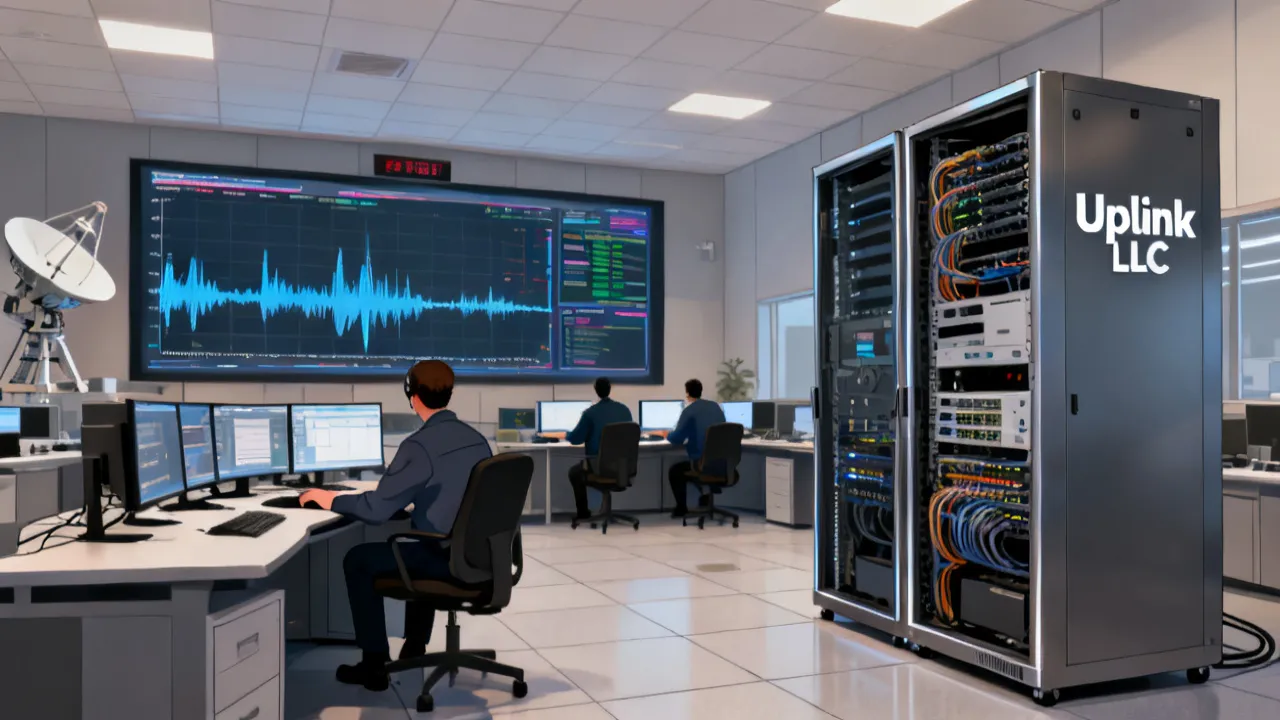
Uplink operations sit at the intersection of RF engineering, network operations, compliance processes, and customer service. In practice, an uplink service may include one or more of the following:
- RF signal preparation: modulation parameters, frequency planning, power levels, and signal conditioning.
- Ground station operations: scheduling, equipment health monitoring, and antenna alignment workflows.
- Transport and handoff: delivering content or data into the uplink chain, and ensuring clean handoffs onward to satellite transponders or managed distribution.
- Monitoring and alerting: operational observability for RF health, link performance, and downstream impact.
- Change control: controlled updates to carrier settings, routing, codecs, encryption configurations, and operational procedures.
From an industry-expert viewpoint, this is not “just a connection.” It is a managed system with interdependent components—where performance is influenced by both technical settings and operational rigor.
An uplink can fail in multiple ways that look similar from the customer side. For example, a service interruption could be caused by a transmitter fault, a power amplifier instability, a misconfigured modulation, an incorrect frequency plan, a monitor/telemetry gap that delays recognition, a backhaul transport issue that starves the encoding/transmission pipeline, or even a security-related access control problem that prevents timely configuration updates. This is why a strong evaluation must focus on operational readiness: not only the ability to transmit, but the ability to diagnose and recover.
When uplink is part of a broader service (broadcast distribution, enterprise connectivity, managed satellite internet, telemetry), the uplink team’s behavior affects more than raw throughput. It affects perceived quality, such as whether the system degrades gradually (and is addressed early) or fails abruptly (and forces emergency actions). It affects operational trust: whether reporting is timely and consistent, whether planned changes happen in predictable windows, and whether escalations produce actionable updates rather than vague reassurance.
It can also affect integration time. If a provider uses rigid assumptions about codecs, transport encapsulation, timing, or monitoring endpoints, the onboarding process may require extended work. By contrast, providers that design interfaces with clarity usually reduce friction during setup and later during upgrades.
3) Provider Selection: Why “Uplink Capability” Means More Than Equipment
When considering Uplink LLC or any uplink supplier, procurement teams often start with high-level descriptions. However, reliability is typically determined by details:
3.1 Operational maturity
Ask whether the supplier has documented operational procedures for incident response, planned maintenance, and escalation. Good providers treat uplink performance as an operational discipline, not a one-time setup.
Operational maturity often shows up in the “boring” parts: how problems are logged, how shift coverage works (if applicable), how responsibilities are handed off between teams, and whether there is a standard approach to verifying transmitter and antenna stability after changes. During evaluation, you should be able to request examples of runbooks, fault isolation checklists, and change approval workflows.
Operational maturity also includes the ability to maintain service during scheduled maintenance. Ask how they handle window planning, whether they can pre-stage configurations, how they prevent accidental drift, and how they confirm the service returns to expected parameters after maintenance.
3.2 Engineering oversight and validation
High-quality uplink services rely on tested engineering workflows—pre-change validation, controlled deployments, and post-change verification. If the provider cannot articulate how changes are validated, you should treat that as a risk indicator.
Validation should not be treated as a single step (“we tested it once”) but as a structured process. Mature providers generally use a sequence: (1) define the change objective; (2) determine the affected parameters; (3) run planned checks or tests; (4) execute in a controlled manner; (5) verify in a pre-defined success state; and (6) confirm operational stability for a period after the change (or until certain indicators are stable).
In a practical sense, you can ask for the “change journey.” For a frequency or modulation change, what do they verify before switching? What do they observe after switching? How do they ensure they can detect drift or partial degradation? If they cannot explain verification criteria, it is difficult to be confident they are preventing regressions.
3.3 Monitoring depth
Monitoring should extend beyond “the link is up.” Industry top practice typically includes indicators relevant to RF stability and service quality—so issues can be detected early and triaged logically.
Monitoring depth is often where uplink providers differentiate. A superficial monitoring approach may only tell you that an interface is reachable. In contrast, RF and service environments benefit from metrics such as signal strength indicators, transmitter health, spectrum or carrier stability indicators (where available), error rates in the downstream stream, latency changes, packet loss, or codec-specific health measures. The key is not just having metrics, but knowing which metrics correlate to service quality and how those metrics are used to trigger action.
During evaluation, it’s useful to ask: what are the top 10 conditions that cause operational attention? How are those conditions detected? How are those detections interpreted? For example, do they recognize a gradual degradation pattern and escalate early, or do they only act once service has already become unacceptable?
3.4 Security and governance
Signals and control channels may require protection commensurate with your risk posture. Look for clarity on access controls, auditability of administrative actions, and secure handling practices.
In uplink operations, security is not only about preventing unauthorized transmissions. It is also about protecting configuration integrity—ensuring that control systems are reachable only by authorized users, that administrative actions are logged, and that sensitive parameters are handled responsibly. Mature providers align access governance with operational needs. For example, if an engineer must take urgent action during an incident, they need safe and fast mechanisms to authenticate and execute changes without weakening governance.
Ask about role-based access, separation of duties, and how audit logs are preserved. Also ask about whether security controls affect operational workflows: are multi-factor authentication and network segmentation used? How do they handle break-glass access? What is the procedure for onboarding and removing administrative users?
4) Industry Context: What “Uplink” Often Covers
Uplink services are used across multiple domains, including broadcast distribution, managed satellite internet, telemetry, and enterprise connectivity models. Each domain has different priorities:
- Broadcast and media distribution: emphasis on consistent signal quality, scheduling reliability, and deterministic delivery expectations.
- Enterprise or managed network connectivity: emphasis on latency, uptime, and operational accountability.
- Data and telemetry workflows: emphasis on integrity, appropriate framing, and controlled operational changes.
In many organizations, the uplink component becomes a critical path dependency. If an uplink fails or degrades unexpectedly, downstream systems may experience service interruptions that extend beyond the ground station itself.
Because uplink requirements vary by domain, you must evaluate Uplink LLC (or any provider) with your use case in mind. A provider that is excellent for one domain may require additional tailoring for another. For example, broadcast workflows may prioritize predictable scheduling and low jitter, while telemetry may prioritize data integrity and controlled update windows that do not risk data schema drift. Enterprise connectivity may prioritize SLA-like uptime reporting, fast incident communications, and consistent configuration management across endpoints.
Another dimension is how “managed” the service truly is. Some offerings are effectively “facility-as-a-service,” where the customer provides much of the configuration and monitoring. Other offerings are “operations-as-a-service,” where the provider handles most operational tasks. To avoid mismatched expectations, the evaluation should include a concrete mapping of responsibilities and the interfaces you will need to provide (or receive).
5) Practical Evaluation Checklist for Uplink LLC
Instead of relying on vague service descriptions, use a structured checklist aligned to real operational needs. Below is an expert-oriented way to evaluate Uplink LLC in terms of what you will likely experience as a customer.
5.1 Define your service boundary
Confirm what your contract covers. For example, you may need clarity on whether the provider is responsible for:
- Signal ingress and preparation
- RF configuration management
- Monitoring and alerting
- Incident response and escalation timing
- Planned maintenance windows
- Handoff support to your downstream systems
When defining the service boundary, do not stop at a high-level list. Push for details about where the provider’s control ends and your responsibilities begin. For instance:
- Who configures the encoding chain—your team, the provider, or both with defined handoffs?
- Who owns the downstream interface monitoring (e.g., demodulators, receiver endpoints, or application-level validation)?
- Who determines acceptance for a “healthy” state after onboarding?
- Who updates documentation when operational details change?
A practical way to evaluate this is to request a scope matrix (even if it is informal at first). Your objective is to remove ambiguity. Ambiguity is the enemy of fast recovery because it slows triage and coordination.
5.2 Evaluate monitoring and reporting
Ask for examples of operational reporting artifacts—what metrics are tracked, how issues are logged, and how you receive updates. Quality providers typically maintain a consistent operational narrative during both normal operations and incidents.
Monitoring and reporting should include both steady-state reporting and incident reporting. Steady-state reporting answers: “How is the service trending?” Incident reporting answers: “What changed, when, and what actions are being taken?”
During evaluation, ask for sample reports with redactions as needed. Look for:
- Whether reporting includes context (what the metric means operationally).
- How often updates are delivered and whether the cadence matches severity.
- Whether reports include timestamps and change references (so you can correlate events to actions).
- Whether the provider uses a consistent incident template.
Also confirm what you will receive automatically versus what requires your request. For example, will you be notified when certain thresholds are met? Will you get near-real-time updates during incidents? Can your team access a dashboard, or do you rely entirely on human updates?
5.3 Confirm change control discipline
Operational changes—frequency adjustments, modulation changes, routing changes, and codec or transport settings—must be handled carefully. Evaluate whether the provider uses a repeatable process for approvals, testing, and verification.
Disciplined change control includes pre-approvals, defined maintenance windows (where applicable), and documented rollback procedures. It should also include post-change verification. But in uplink operations, the “post-change verification” often matters more than teams expect. A configuration can appear to work immediately yet drift or introduce subtle errors later.
Ask specific questions such as:
- How is a proposed change packaged (what information is required for approval)?
- Who approves changes, and how is segregation of duties handled?
- What are the verification criteria? (e.g., signal lock confirmation, error rate thresholds, service quality indicators.)
- What is the rollback time objective, and how is rollback executed?
- How are change outcomes documented and audited?
If Uplink LLC can describe these workflows clearly, you have evidence of engineering governance. If they respond with high-level statements but cannot describe the mechanics, you may be taking on risk that will surface during your first “real-world” change event.
5.4 Validate escalation and incident response
Ask how quickly the provider can respond to anomalies, what constitutes an incident vs. a degradation, and how escalation is handled when multiple systems are implicated.
Escalation should not be treated purely as speed. It should be treated as structure. A good incident process includes:
- Clear severity definitions (what counts as SEV-1 vs SEV-2, etc.).
- A known escalation tree (who gets paged and when).
- Defined update cadence during incidents.
- Explicit roles for diagnosis vs communication.
- Evidence-based actions (telemetry-driven triage, not guesswork).
During evaluation, you can ask for a de-identified incident example: what happened, what signals indicated the issue, how the team responded, what was learned, and whether improvements were made to prevent recurrence.
Also clarify how multi-party incidents are handled. In many uplink scenarios, the problem might involve your content pipeline, your network provider, the satellite transponder path, or the ground equipment. Mature providers establish coordination patterns so you don’t have to discover responsibilities during a crisis.
5.5 Review documentation quality
Documentation is not bureaucracy; it is a reliability tool. Look for clarity around interfaces, operational responsibilities, contact pathways, and maintenance procedures.
Documentation quality includes:
- Interface definitions: what parameters exist, where they are set, and how they are read.
- Operational runbooks: step-by-step guidance for common issues and fault isolation.
- Operational contact pathways: who to reach for what, including off-hours support if needed.
- Maintenance procedures: how equipment is tested before and after maintenance.
- Security documentation: access policies and audit expectations.
A mature provider doesn’t only provide documentation at onboarding. They also update it when changes occur. Ask how they ensure documentation stays current—because stale runbooks are worse than no runbooks during incidents.
6) Comparison Table: Sourcing Criteria, Sources, Steps, and Requirements
The following comparison framework is designed to help you assess uplink providers—including Uplink LLC—by evaluating common operational requirements. (No external links are included in the table, per your instructions.)
| Criteria | Industry Source (Reference Type) | Step-by-Step Evaluation Approach | Conditions / Requirements to Confirm |
|---|---|---|---|
| Operational responsibility boundaries | Provider service documentation; standard service contract structures | 1) Request a scope matrix. 2) Map your responsibilities vs. theirs. 3) Identify any ambiguous “shared” steps. | Written scope clarity; defined handoff points; documented RACI (who does what). |
| Incident response process | Operational top practices; incident management frameworks | 1) Ask for example incident timelines. 2) Verify escalation paths. 3) Confirm what telemetry triggers action. | Documented escalation; clear roles; measurable update cadence during incidents. |
| Monitoring and performance measurement | Network operations practices; quality monitoring methods | 1) Request monitoring indicator definitions. 2) Confirm frequency of alerts. 3) Review how anomalies are triaged. | Defined metrics; ability to provide service quality context; consistent reporting format. |
| Change control and validation | Engineering governance; disciplined change management practices | 1) Ask how changes are reviewed. 2) Verify test or rollback approach. 3) Confirm post-change verification. | Pre-approval workflow; rollback procedures; change logs and auditability. |
| Security and access controls | Risk management and secure operations guidance | 1) Request access control model. 2) Confirm admin action logging. 3) Ask about segregation of duties. | Role-based access; audit trails; secure handling of control channels. |
| Compliance readiness (as applicable) | Regulatory and compliance documentation (domain-specific) | 1) Identify which compliance obligations apply to your use case. 2) Ask for evidence of alignment. 3) Review how exceptions are handled. | Documented policies; evidence of adherence appropriate to your sector. |
| Service continuity planning | Business continuity and operational resilience frameworks | 1) Ask about redundancy strategy. 2) Review planned maintenance approach. 3) Confirm how continuity is validated. | Continuity procedures; tested failover or mitigation steps (where relevant). |
While the table helps structure the evaluation, it is also useful to interpret each row in terms of what could go wrong. For example, if you lack responsibility boundaries, you might face delays in diagnosis. If incident response processes are unclear, you may get slow updates, mismatched triage, or repeated troubleshooting attempts. If monitoring is shallow, you may only learn about degradation after it impacts customers. If change control is weak, you may create avoidable outages when “normal maintenance” becomes risky.
Use this table as a starting point and push each criterion for concrete evidence. Evidence might include sample reports, de-identified incident summaries, change workflow artifacts, security policy excerpts (as permitted), or documentation samples.
7) Step-by-Step Guide: How to Compare Uplink LLC to Other Suppliers
To keep your evaluation grounded, follow a structured process. This is especially helpful when teams are comparing multiple uplink providers or managed service packages.
Step 1: Translate your business need into uplink requirements
Start by clarifying what you are delivering and how “success” is measured. For example, is the priority consistent broadcast quality, deterministic delivery windows, or network uptime under varying load patterns?
A common mistake is to evaluate uplink providers using network-style assumptions (e.g., “we need low latency”) without connecting those requirements to uplink operational parameters. Instead, connect your business outcomes to technical and operational realities. If you need deterministic delivery windows for scheduled broadcast, then you should evaluate scheduling reliability, maintenance window discipline, and rollback procedures. If you need uptime for enterprise connectivity, then evaluate incident communications, escalation readiness, and continuity planning.
Consider also your internal operational maturity. If your team already manages part of the pipeline (encoding, transport, or downstream verification), you need a provider that integrates well with your operational model. If you want a fully managed approach, you need a provider that assumes ownership and provides clear operational outputs.
Step 2: Define acceptance criteria and quality expectations
Quality should be specified as measurable outcomes where possible. In many operational scenarios, you can define acceptance criteria related to service stability, reporting cadence, and response behavior during incidents.
Acceptance criteria can include both performance and process. Performance criteria might include acceptable error rates, stable signal parameters, or stable link indicators. Process criteria might include response-time behavior, update cadence, documentation quality, and post-incident debrief structure.
Make sure acceptance criteria are testable. For instance, “stable service quality” should be paired with indicators and measurement methods. Similarly, “fast response” should be paired with severity definitions and communication expectations.
Step 3: Request a scope and responsibility matrix
Ask suppliers to map their services to your operational responsibilities. This is where many procurement gaps surface, especially if customers assume the provider handles a task that is actually theirs.
When reviewing the scope matrix, pay attention to “shared” responsibilities. Shared responsibility is not inherently bad, but it must be structured. If both parties “co-own” a process without a defined RACI, you may end up with stalled troubleshooting during incidents.
Also watch for scope drift over time. For example, a provider might handle initial setup fully, but later expect you to take over certain maintenance tasks. If that expectation is not clearly written, you may experience unplanned operational burdens later.
Step 4: Review monitoring and escalation details
Compare how different suppliers handle alerting and escalation. The top signal quality is often a result of early detection and disciplined triage rather than heroic troubleshooting during prolonged outages.
Ask for the operational “feedback loop”: how telemetry is collected, how thresholds are evaluated, how alerts are triaged, and how those alerts translate into action. If a provider can show you how monitoring is used to prevent outages or reduce time to recovery, you have a stronger basis for trust.
During comparison, it’s useful to assess whether alerting is customizable. If your organization has specific operational constraints or preferences, you should clarify whether you can tune thresholds, reporting formats, and escalation behavior.
Step 5: Validate change management workflows
Ask for the process used for configuration changes and how those changes are verified. A disciplined rollback approach is a maturity marker, not an optional extra.
In uplink environments, configuration changes can have cascading effects. For example, a change to RF parameters can influence how downstream receivers lock; a change to encoding settings can influence error rates; a change to security configuration might influence access to control systems; and a change to transport might influence timing and buffering behavior.
When validating change management, compare how suppliers handle risk. Look for structured pre-change reviews, clear test plans, explicit rollback triggers, and post-change verification steps. Also ask about how the provider handles emergency changes—do they still follow governance, or do they bypass it? If emergency procedures exist, they should still be documented and auditable.
Step 6: Confirm security and administrative safeguards
Even when the technical uplift is strong, security misalignment can create operational risk. Confirm access controls, administrative logging, and how sensitive settings are protected.
During comparison, request clarity on:
- How administrators are authenticated (e.g., multi-factor authentication).
- Where administrative actions are logged.
- How access is granted and removed.
- How sensitive RF and control parameters are protected.
- How secure channels are used for remote operations (where applicable).
Also confirm whether the provider has a security incident response process that aligns with your expectations. If a security event occurs, you need to know how operations will be protected and how you will be informed.
Step 7: Pilot or staged onboarding (where feasible)
If your environment allows, a staged onboarding can help confirm compatibility between your workflows and the provider’s operational methods. Even short pilots can reduce good friction.
A pilot can be more than a technical test. It can also be an operational test. Observe:
- How onboarding tasks are scheduled.
- How your team is involved (or not) and whether communication is clear.
- How the provider validates service health after changes.
- How quickly issues are identified and how information is shared.
- Whether the provider’s operational rhythm matches your internal needs.
If pilots are not feasible, request a structured onboarding plan with measurable checkpoints and signoffs.
8) Conditions and Requirements to Consider Before Signing
Operational contracts vary, but uplink services typically require alignment on at least the following conditions:
- Clear service scope: precisely where your responsibilities begin and end.
- Operational contact points: who responds, how escalation occurs, and expected response behavior.
- Change windows and communication: how planned changes are scheduled and communicated.
- Reporting cadence: what gets reported routinely and during incidents.
- Testing and acceptance: how you validate the service after setup and after meaningful changes.
As an industry lens, these requirements reduce ambiguity—the main driver of operational friction in complex uplink environments.
Before signing, you may also want to ensure that your contract and operational plan define responsibilities for the following scenario types:
- Partial degradation: service remains reachable but quality decreases. Who investigates, and how quickly is escalation triggered?
- Complete outage: uplink carrier fails or transmitter is down. Who restores service, and what is the expected recovery communication cadence?
- Configuration drift: changes occur without proper governance (intentional or accidental). How is drift detected and remediated?
- Planned migrations: move to new parameters, new equipment, or new operational processes. Who leads the migration and how is acceptance defined?
- Emergency changes: how are emergency changes performed while maintaining security and auditability?
Also ensure that you can obtain operational evidence you need. For example, you might need incident timelines, change logs, or confirmation that certain checks were performed. These artifacts are useful for your internal audits and continuous improvement.
9) Expert Analysis: Common Failure Modes in Uplink Deployments
Understanding typical pitfalls helps you ask better questions. While every deployment has unique constraints, uplink failures often stem from categories like these:
9.1 Misaligned responsibilities
When customers and providers have unclear roles, issues can linger because troubleshooting is delayed by uncertainty over ownership. A well-defined scope matrix is one of the simplest risk reducers.
Misaligned responsibilities can show up as:
- Slower incident identification because people wait for the “other side” to confirm ownership.
- Repeated configuration changes during triage due to uncertainty about who last changed what.
- Post-incident disputes about what was covered under the contract.
To avoid this, ensure your evaluation captures responsibility boundaries down to actionable operational steps. For instance, not only “monitoring is provided,” but also “who interprets the monitoring results and initiates triage.”
9.2 Weak change governance
Even minor configuration changes can affect performance. Without a disciplined approval and verification process, the uplink chain can experience avoidable degradations.
Weak change governance can create subtle, long-lived issues. An example pattern might be: a change improves one aspect (e.g., transmitter power setting) but inadvertently causes other parameters to drift (e.g., modulation stability or receiver lock margin). If post-change verification is not robust, the issue may only surface after some operational load or after downstream systems experience intermittent failures.
Ask providers how they prevent “silent changes.” For example, do they rely on manual configuration alone, or is there version control and auditability? How are configuration backups managed? How do they ensure that rollback is prepared before changes are executed?
9.3 Insufficient monitoring granularity
If monitoring focuses only on binary availability (“up/down”), teams may miss gradual degradation signals. Deeper observability shortens time to detection and improves resolution planning.
Granularity is important because uplink performance problems often develop as trends rather than sudden flips. A transmitter might drift; temperature changes might affect component stability; a backhaul path might degrade intermittently; and downstream receivers might become marginal until conditions worsen.
If monitoring is shallow, incident severity might be misclassified—what is actually a gradual degradation might only be detected after it becomes a total outage. Mature providers typically track multi-dimensional indicators so they can catch trends early.
9.4 Incomplete incident playbooks
If incident response lacks a consistent playbook, teams may rely on ad-hoc decisions. Mature providers structure response activities so that actions are repeatable and auditable.
Incomplete playbooks can cause:
- Inconsistent troubleshooting steps across responders.
- Loss of operational context over long outages.
- Repeated actions that worsen the situation because no “known-good sequence” exists.
During evaluation, ask about playbook structure: do they have fault isolation steps keyed by symptom? Do they maintain a decision tree? How do they document what worked and what didn’t for future learning?
9.5 Security and access friction
When secure access is not aligned with operational needs, teams may hesitate during urgent events. Balanced access controls and clearly defined workflows help teams act quickly without compromising governance.
Security friction often appears when teams cannot quickly authenticate or when access approvals take time during emergencies. In mature systems, security is designed to be operationally usable: role-based access, pre-approved admin roles, secure remote access patterns, and clear break-glass procedures. This allows rapid action without undermining auditability.
Ask how emergency access works. Who is authorized? How is it logged? How is it reviewed after the incident? If security is too restrictive without a defined emergency path, you may face slow recovery.
10) FAQs about Uplink LLC and Uplink Operations
Q1: What does an “uplink” typically include in a managed service?
An uplink service often includes ground-based signal transmission preparation, RF configuration, monitoring, and operational support. The exact scope depends on the provider contract—some vendors focus on facility operations, while others manage broader end-to-end workflows.
To clarify in your evaluation, treat “uplink” as a set of components rather than a single service label. Ask whether Uplink LLC handles the signal from your ingress point through transmitter operation, and whether they also support integration with your downstream verification or service delivery chain.
Q2: How can I compare Uplink LLC offerings with other suppliers objectively?
Use a structured comparison approach: scope boundaries, monitoring depth, change control discipline, escalation behavior, reporting cadence, and security governance. Request documentation and evidence of processes rather than relying on general descriptions.
In objective comparison, it helps to assign weighted criteria aligned to your risk and operational priorities. For example, if you operate time-critical broadcast, monitoring depth and change windows might be weighted higher. If you operate enterprise connectivity with strong internal security requirements, access controls and incident communication might be weighted higher.
Q3: What metrics should I ask for to understand service quality?
Ask for the provider’s relevant indicators for RF and link health, how they detect anomalies, and how they report performance context. The goal is to understand how quickly issues are recognized and how reliably they are traced to actionable causes.
Be specific about what you want metrics for. Examples of metric categories to request include:
- RF health indicators: transmitter stability, component health, power levels, and related system readings.
- Link indicators: carrier/signal quality indicators relevant to your downstream receivers.
- Service quality indicators: error rates, lock stability, and downstream stream health indicators.
- Operational indicators: alert counts, incident durations, and recovery time patterns (as available in de-identified form).
Q4: Do uplink operations require rigorous change control?
Yes. Uplink chains are sensitive to configuration changes across RF and network parameters. Disciplined change control—including pre-validation, rollback planning, and post-change verification—helps prevent avoidable degradations.
Rigorous change control is also important for auditability. If you need to demonstrate compliance or perform internal reviews, you will want evidence that changes were reviewed and verified, and that outcomes were documented.
Q5: What security topics should be discussed during supplier onboarding?
Discuss administrative access controls, audit logging, secure handling of sensitive configurations, and how operational teams are granted and monitored access to control systems.
You should also clarify:
- Whether remote operations use secure channels.
- How authentication methods are enforced.
- How segmentation and least privilege are applied.
- How sensitive configuration artifacts are stored and protected.
Q6: Can an uplink provider improve reliability through processes alone?
Processes have major impact. Even with competent hardware, reliability often improves with disciplined monitoring, escalation playbooks, careful change governance, and clear responsibility definitions—all of which are operational rather than purely technical.
That said, processes work best when paired with competent engineering. Mature processes also feed engineering improvements over time: if incidents happen repeatedly, the provider should analyze root causes and refine monitoring thresholds, update runbooks, and adjust change practices.
Q7: Is satellite communication performance predictable?
Satellite communication performance involves operational variability. You should evaluate how the provider measures performance, communicates risks or degradations, and maintains a consistent response process when conditions change.
Even with predictable procedures, satellite conditions can vary and may create performance changes. The evaluation should therefore also consider how the provider interprets conditions, communicates risks, and adapts operations within the defined governance model.
11) Reliable Sources and References (No Unverified Claims)
To keep the discussion evidence-aligned, this article reflects widely used operational and engineering practices. For broader background on communications reliability and network operations concepts, you may consult recognized standards and public guidance from organizations such as the International Telecommunication Union (ITU) and NIST for security and risk management. For incident and service management principles, widely referenced operational frameworks can provide context on how disciplined processes reduce downtime and improve response quality.
Note: This guide does not provide performance statistics or price claims about Uplink LLC because no verified, citable pricing or measurable performance figures were provided in your prompt. If you share specific package details, geographic coverage, or contract terms, I can help you build a comparison grounded in those concrete facts.
In many procurement processes, teams ask for performance claims too early, before the scope and acceptance criteria are defined. A better approach is to agree on measurable indicators first, then ask for evidence that the provider can meet those indicators. This avoids relying on promises that cannot be operationalized into measurable outcomes.
Evidence-based evaluation can include structured interviews, review of documentation artifacts, operational walk-throughs, and—where feasible—trial exercises such as a simulated incident or a controlled onboarding test. Those exercises often reveal how a provider thinks and how their operations behave under pressure.
12) Conclusion: A Buyer’s Mindset for Uplink LLC and Uplink Services
When you evaluate Uplink LLC or any uplink supplier, the very defensible approach is to judge operational maturity: clear scope, disciplined change control, deep monitoring, robust escalation procedures, and security governance. Uplink operations succeed when engineering and operations function as one system—so the customer’s service experience remains stable, understandable, and accountable.
If you want, tell me your use case (broadcast, enterprise connectivity, managed service, or telemetry), your expected service window, and what “success” means to your team. I can then tailor an evaluation checklist and a request-for-information (RFI) template specifically for your environment.
In the meantime, use the evaluation approach described throughout this guide as a practical lens. Focus less on vague assurances and more on mechanisms: how changes are validated, how alerts lead to action, how incidents are communicated, and how access is governed. When a provider can demonstrate these elements with clarity, you can make a procurement decision with better confidence and fewer surprises once operations begin.